Baseten makes serverless loops generally available for post-training – Unite.AI
Baseten announced on November 6, 2026 that Serverless Loops is generally available, opening up its managed SDK for supervised tuning and reinforcement learning on open models to everyone. The service uses per-token training billing and provides a direct path from checkpoints to dedicated Baseten inference.
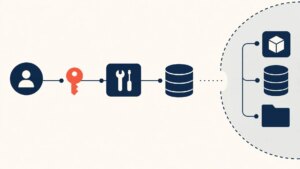
Loops is built around a division of labor: users provide the training signal, while Baseten manages the GPUs, kernels, model architectures, and distributed training backend. The Python SDK trains LoRA adapters with frozen base model weights. Users choose the base model, LoRA rank, learning rate, loss function, data or environment, and algorithm; Baseten manages the trainer, sampler, weight synchronization and support infrastructure.
A compatibility pack preserves Tinker imports and basic training and sampling calls for teams migrating existing scripts. The migration guide still modifies authentication in a Baseten API key, returns checkpoints as paginated file URLs, requires inline image input, and fixes LoRA module coverage per model family. Compatibility covers the training API while leaving several infrastructure-specific details that teams can modify.
Serverless models and billing
The serverless catalog contains three models: Qwen/Qwen3.6-35B-A3B AND zai-org/GLM-5.3-Flash for text and vision, e zai-org/GLM-5.3 for text only. Each supports a maximum sequence length of 262,144 tokens. GLM-5.3 does not support long context configuration cross_entropy OR dpo losses. Dedicated mode covers the largest model catalog, bills GPU time, and adds controls for replications, hot reuse, and spot capabilities.
Serverless executions use shared capacity without requiring GPU reservations and billing for tokens used in training and sampling. There is no nominal charge for time spent reading results, changing a reward feature, or sitting idle. Selecting the default mode can fall back on dedicated capacity for an unsupported model, LoRA rank, or sequence length, or when one run reuses another run’s distributions. Setting the scope to serverless instead causes an unsupported request to fail.
Enabling the template does not guarantee provisioning. Specific workspace access, unavailable GPUs, and organization trainer limitations can still block a run, giving the pay-per-token model a number of practical capacity limits beyond the published catalog.
Checkpoints and production inference
The quickstart exposes four main operations: forward_backward for loss and gradient work, optim_step for adapter updates, sample by generation and save_state for the resumption of training. Publishing sampler weights creates a deployable checkpoint and an associated sampling client. A separate save_state the operation preserves the model and the state of the optimizer. The first sampling request can take several minutes while the serverless capacity is booted up, a practical consideration for short experiments.
A sampler checkpoint is deployed as a base model with the trained LoRA adapter loaded. Checkpoints survive their executions and can be deployed via CLI, REST API, or dashboard using a Hugging Face access token, as deployment offloads baseline weights. The resulting OpenAI-compatible endpoint bills its GPU while it is active. Deleting that distribution stops GPU charging without eliminating the checkpoint; Disabling looping does not remove the distribution.
For GA, Baseten improved the handling of transient network errors and GPU failures, reduced startup costs, and accelerated weight transfers between trainers and samplers. Baseten says these changes support more concurrent customer workloads, and that its production inference stack serves more than 15 billion requests per day. The production path includes autoscaling, deployment management, and inference metrics, while users can download weights in the Hugging Face Safetensors format.
Validation and first customer workloads
Baseten says it validated the service with numerical tests and end-to-end reinforcement learning experiments using τ-bench tasks in the retail, airline and banking industries, followed by evaluation of difficult tasks. The τ-bench project describes a benchmark for evaluating whether agents can converse with users, invoke tools, retrieve knowledge, and follow policies in business domains, with results compared to verifiable database results.
Baseten reports that NVIDIA post-trained Nemotron Super 3.5 VL on text and vision tasks, improving intent classification accuracy from 76.8% to 94% and achieving 87% F1 validation on receipt extraction; the work also included reinforcement learning for counting visual objects. Datadog uses the multi-turn RL agent to test training ideas for its SRE agent and Ambience Healthcare’s post-trained models to correct clinical transcription errors and capture medical terminology and formatting accurately.
LangChain Labs offers post-training models on agent traces for LangSmith Engine, including work that reads a GitHub repository to diagnose a problem and drafts the prompt or code change for a pull request. It can switch to a smaller open weight model to classify traces based on failure mode and severity or map them to existing problems. LangChain’s workflow illustrates how application behavior becomes the focus of training, with model size and task specialization chosen based on the job.
Customer accounts document usage prior to the GA announcement and show the expected infrastructure cycle: application data becomes training input, checkpoints are evaluated, and selected models move to production. For infrastructure teams, the cost constraint is equally clear. Supported serverless executions avoid GPU reservations and token charges at idle, while a live inference endpoint continues to bill its GPU; The serverless catalog and workspace capacity determine where the serverless option applies.
Post Comment