WorldOracle tests whether world models can reliably predict real-world executions
Key points
- WorldOracle is a benchmark for action-conditioned world models (ACWM) that evaluates each model’s intended implementation compared to coupled execution in the real world, with both starting from the same initial observations and following the same sequence of actions.
- Seven representative models were evaluated; arm movement was predicted relatively well, but object positions and movements often deviated from reality and performance degraded compared to full task sequences.
- The platform opened to developers on October 16 and accepts both open-weight and closed-source models.
In one WorldOracle case, the robot’s grasp failed, but the world model predicted a successful choice. Credit: [WorldOracle team / AgiBot]
In one case presented by WorldOracle, a robot missed its grasp, but the world model predicted that the robot successfully picked the fruit.
By considering the opening frame and action sequence of a real manipulation episode, the model generated an implementation that looked plausible on screen but differed from the actual execution. The described success never happened in reality.
Researchers from Princeton University, the University of Texas at Austin, the University of Toronto, NVIDIA, and AgiBot have jointly introduced WorldOracle, a benchmark specifically designed to evaluate action-conditioned world models (ACWMs) by comparing their predictions to real-world runs that start from the same initial observations and follow the same action sequences.
The team evaluated seven representative models – including DreamDojo, Cosmos 3, IRASim and GE-Sim 2.0 – and identified two major issues. First, while the motion paths of robotic arms are relatively well predicted, the positions and movements of the manipulated objects can still deviate from reality. Second, models that perform well over short horizons can deteriorate significantly over full operational sequences.
On October 16, WorldOracle, an evaluation platform for action-driven world models, officially opened to developers. The research team collected real episodes of manipulation in advance, recording both videos and actions. Developers use the initial frames and action sequences provided in the evaluation set to generate predicted videos and send them to the platform, which evaluates each submission against the corresponding real-world execution record. The results show whether a model accurately predicted the consequences of actions, helping developers identify weaknesses and verify improvements.
Project page:
Paper:
How do the models of the seven worlds behave?
The arm movement is correct, but the objects do not always follow
The predicted motion of a robotic arm approaching a fruit and closing its gripper can match its actual motion very closely, but the model can still incorrectly predict whether the fruit will be lifted and where it will move next. To evaluate the two separately, the research team compared the position and movement of the robot’s arm and the manipulated object in each predicted video with the real-world recording and scored them individually.
Spatial alignment scores for the robot arm and the manipulated object. Credit: [WorldOracle team / AgiBot]
The results show that all five models evaluated on data from the human-operated AgiBot G2 scored higher on the arm than on the object. In other words, even when the arm in the generated video follows the indicated actions well, the position and movement of the object may still deviate from reality. IRASim scored 78.8 on the robotic arm but only 29.1 on the manipulated object, while Cosmos 3 scored 89.4 and 45.4, respectively. The remaining models showed gaps of varying magnitude.
Accuracy decreases as the implementation horizon increases
Time presents a second challenge. Completing an ongoing task often requires multiple grasps, placements, and adjustments, and the state of the object left behind from one interaction becomes the starting point for the next. If a model comes close to reality it must then be tested throughout the entire process.
WorldOracle evaluates both the first 30 seconds of each trajectory and the complete long sequence.
WorldOracle-SV scores of the same models in the two evaluation horizons. Credit: [WorldOracle team / AgiBot]
In the same teleoperation dataset as the AgiBot G2, the WorldOracle-SV scores of all five models decreased. DreamDojo fell from 50.56 to 27.08 and Cosmos 3 from 53.99 to 26.60, nearly halving in both cases. GE-Sim 2.0 fell from 73.86 to 63.33; it had the highest score among the five models on both horizons and the lowest decline across the entire sequence.
The relative ranking has also changed. IRASim scored lower than Ctrl-World, DreamDojo, and Cosmos 3 in the first 30 seconds, but mostly three in the entire sequence.
What can WorldOracle measure?
WorldOracle Scoreboard: Real actions are recorded, the model predicts what follows, and the outcome is evaluated against real execution. Credit: [WorldOracle team / AgiBot]
Accurately predicting failure earns high marks
WorldOracle starts from pre-collected recordings of real manipulations. A model is given the initial frame and action sequence and generates a predicted video, which is compared to the real execution of the same actions.
What the models need to predict includes missed catches, falls and spills. If a trade fails in reality, accurately predicting the failure counts as a correct prediction.
Failed executions therefore serve as an important class of test samples: they reveal whether a model follows the given actions and their consequences, or whether it automatically executes a successful version of the task.
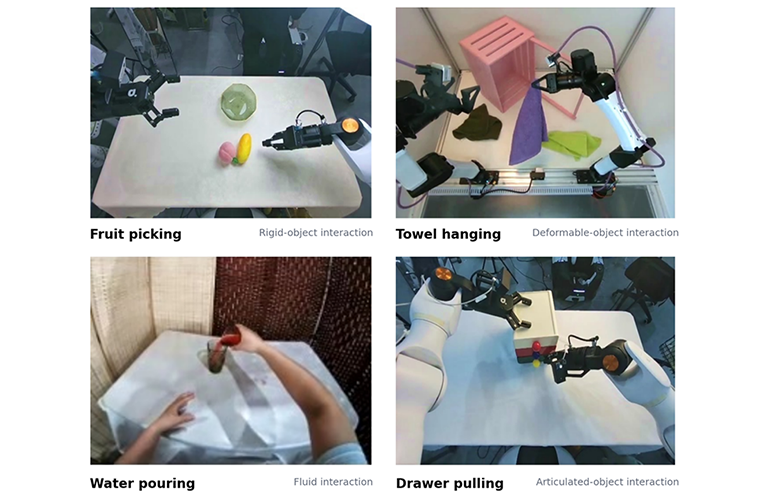
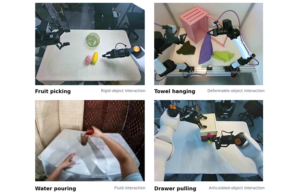
The benchmark covers two robot embodiments, AgiBot G2 and YAM, as well as first-person human hand manipulation. Four tasks (picking fruit, hanging towels, pouring water, and pulling drawers) involve interacting with rigid, deformable, fluid, and articulated objects, respectively. Task coverage varies depending on the embodiment, as defined in the evaluation set.
The human hand setup is intended for world models that can accept hand motion input, testing whether a model can predict subsequent object changes and interaction outcomes from a recorded sequence of hand poses. Models with egocentric world-shaping capabilities are evaluated zero-shot in this context, without additional hand adaptation data provided by the platform.
Real performance footage for the four task types. Credit: [WorldOracle team / AgiBot]
The data comes from two sources. The first is human-operated data collection, including robot teleoperation trajectories and human hand manipulation trajectories. The second is policy implementation, where an autonomous policy controls a real robot.
When a robot performs autonomously, it can produce pauses, jitter, and motion corrections that differ from human operation. Including such data helps verify whether a global model remains accurate when faced with actions from different sources.
The platform offers three paths:
- WorldOracle Core: evaluates the predictions on the first 30 seconds of the trajectories operated by man.
- WorldOracle Policy: evaluate predictions over full episodes of autonomous policy deployments on AgiBot G2.
- WorldOracle-long: evaluates sustained prediction over long human-operated complete sequences.
The WorldOracle study compares several benchmarks of the embodied world model. Of these, WorldOracle is the only one that simultaneously covers action sequence inputs, real-world execution data, failure cases, long-horizon interaction, multiple embodiments, multi-view evaluation, and autonomous policy implementations.
Decomposing forecast error: results and process
The predicted and actual positions of the robot arm can closely match even when the model errs in the fruit grasping state; two final states may resemble each other while the paths that led to them differ. A single score is unlikely to capture such differences.
WorldOracle monitors forecasts with four complementary metrics:
- Correctness of physical state: checks whether the position of the objects, the grip states and the transfer of the liquid at the end of each interaction correspond to the real result.
- Spatial alignment of the interaction: checks whether the positions and motion paths of objects, robotic arms or human hands are consistent with the real process.
- Key interaction area fidelity: focuses on regions such as the object, gripper and hand, combining pixel-level, perceptual and semantic similarity to reduce the influence of large background areas on the score.
- Multi-view action consistency: For models that support multi-view output, checks whether the robot’s movement through synchronized camera views aligns with real-world execution.
The first three metrics with equal weights are averaged to form the WorldOracle-SV score (single view); for multi-view evaluation, the fourth metric is added and the four are weighted equally again. Secondary scores are also preserved, allowing developers to distinguish problems in state prediction, motion trajectories, and local details.
To validate the parameters, the researchers asked 119 participants to compare 128 pairs of predicted videos. The four metrics agreed with human choices about which prediction was best 88.1% to 93.2% of the time.
The researchers also note the limitations of the benchmark. Measures how closely a prediction matches a single recorded actual execution. For fluids, deformable objects, and stochastic contact, the same action can lead to several plausible results, and a single reference cannot fully describe that range.
Training support also differs between embodiments: AgiBot G2 models use a benchmark-specific training set, YAM models use public data, and the human hand setup is zero-shot evaluated. Scores across the three contexts should therefore not be used directly to judge embodiment difficulty or cross-embodiment generalization.
How can developers participate?
Open proposals provide concrete feedback to the model iteration
WorldOracle supports both open-weight and closed-source models. After registration and approval, developers choose a track based on embodiment or manipulation by setting model supports, generate and upload expected videos following the submission guide, and view composite scores, subscores, and comparisons.
For model iteration, this feedback can be tied to specific questions: Did a change make the object’s motion more accurate? Has it reduced mispredictions of failed trades? Does the improvement persist as the forecast horizon grows?
Whether futures generated by a world model can be relied upon needs to be tested against their actual execution. WorldOracle turns that test into a unified set of tasks, data, and scoring methods, giving developers a foundation to compare models, identify errors, and verify improvements.
Project page:
Presentation Guide: Presentation/
Content sponsored by WorldOracle
Post Comment