Unemployment Labs reports Blackwell models in Chinese artificial intelligence models – Unite.AI
An analysis by Will DePue’s Unemployment Labs, published on November 12, 2026, found initialization patterns consistent with NVIDIA’s export-controlled Blackwell GPUs in six open-weight models from DeepSeek, Moonshot AI, MiniMax, and Ant Group.
The analysis maps DeepSeek-V4-Flash and MiniMax-M3 to initialization on B200 or B300 chips, and DeepSeek-V4-Pro, Kimi K3, Kimi K3.1-Pro, and Ling-3.1-flash with GB200 or GB300 chips. The matches identify the hardware arrangement behind the initial weights; whether those chips also performed training is a separate inference.
Subsequent releases place the apparent changes in time. DeepSeek-V3 produced a Hopper reading in December 2024, followed by the two V4 models with Blackwell reading in April 2026. Moonshot AI’s Kimi K2.5 read as Hopper in January 2026 before K3 in July 2026; MiniMax-M2.7 and M3 followed the same pattern in April 2026 and June 2026, respectively; Ant Group’s Ling-3.0-flash and Ling-3.1-flash did so in August 2026 and October 2026.
The model was not universal. More recent readable models from Alibaba, Zhipu, Tencent, Xiaomi, and StepFun have produced Hopper rather than Blackwell reads.
How initialization reveals a hardware layout
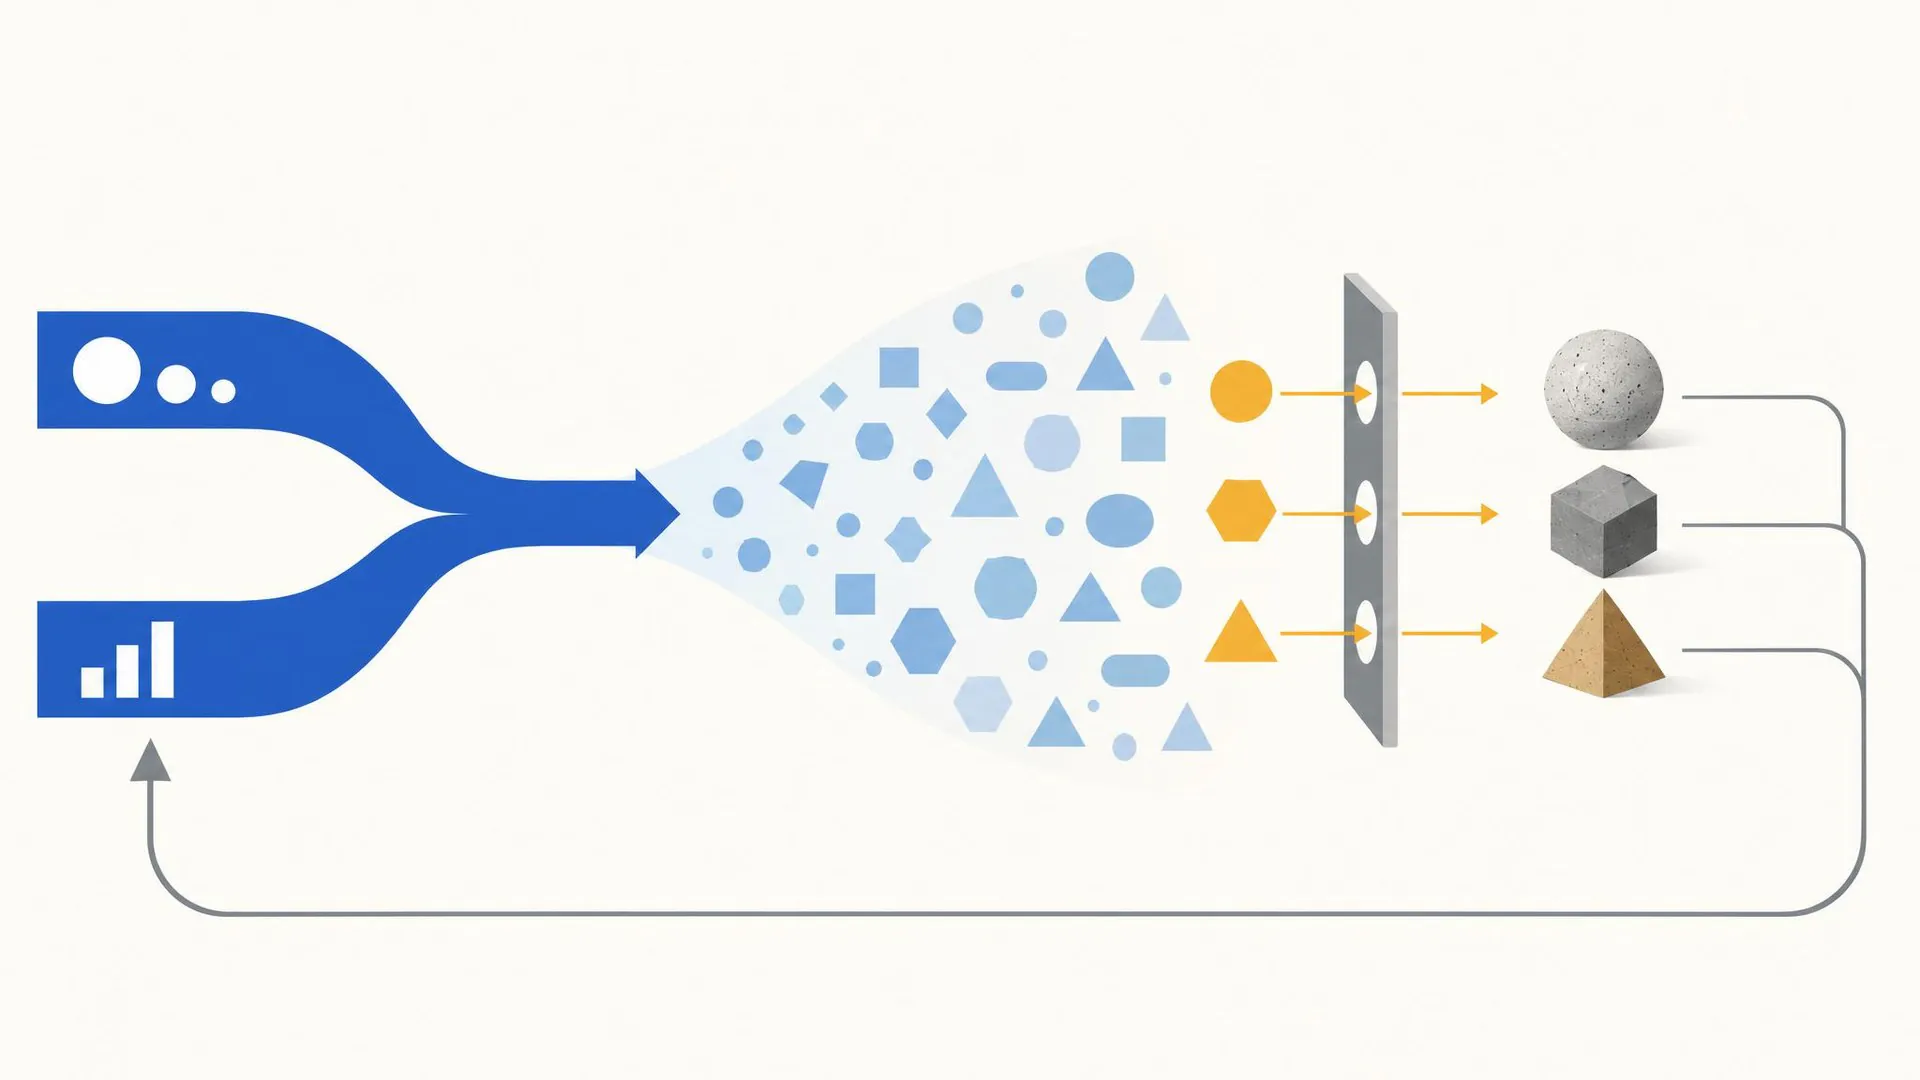
The technique begins with weights, the numerical parameters that training regulates. Before training, the PyTorch/cuRAND setup we examined uses the Philox generator to produce repeatable values from a seed. GPU threads distribute these values across weight positions, and a large enough initialization uses 2,048 threads per streaming multiprocessor (SM). Changing the SM count therefore changes where the same generated numbers end up.
In the tested configurations, the H100 SXM, H200, and H800 Hopper chips have 132 SMs and 270,336 threads; The B200 and B300 chips have 148 SMs and 303,104 threads; The GB200 and GB300 chips have 152 SMs and 311,296 threads. A reading identifies one of these groups, not a specific chip within it.
Weights reserved for words or symbols absent from training can preserve the initial values almost exactly, while trained weights can maintain a weaker statistical relationship with those values. Investigators select a seed and layout on a set of weights, then test the unchanged combination on a separate set excluded from the search.
According to its statistical model, the report estimates that about 6 trillion seed-and-layout combinations would produce a stronger than expected probabilistic match of about 8 sigma, a statistical measure of distance from random variation. The strongest results for the identified models range from 49 to 1,385 sigma, and every single test included achieves at least 20 sigma.
Physical checks and training scale estimates
DePue’s physical chip replicas provided another check. Using the seed retrieved from DeepSeek, an H100 reproduced the preserved values of DeepSeek-V3 but not those of V4-Flash, while a B300 did the opposite. On the B300, unmodified PyTorch reproduced 461 of the 469 selected V4-Flash lines with correlations above 0.99, including 445 complete bitwise line matches. A rented GB200 reproduced all 13 Kimi K3 rows preserved with the Moonshot seed; changing one of the retrieved seeds with one resulted in no matching rows.
The report states that the method was agreed upon in all 24 cases in which a developer publicly named a specific model’s hardware, while warning that 11 involve step-zero checkpoints and their models are not independent. This makes the comparison a consistency check rather than a measured accuracy rate.
Kimi K3.1-Pro uses the K3 seed and could be a K3 checkpoint with additional post-training. Assuming the initialization hardware has also performed training, DePue estimates five distinct final runs of approximately 500 to 3,000 Blackwell GPUs each, typically over the span of two to three months. The calculation splits the training computation by chip throughput at 35% utilization, using DeepSeek’s disclosed token counts and weight-based token estimates for the other models. Applying the same arithmetic to DeepSeek-V3 produced 2,000 to 2,500 chips, compared to the 2,048 claimed by DeepSeek.
Limits for the application of export controls
A match is only about initialization; cannot inventory all processors used during subsequent training. A lab might create initial values on a system and transfer them, mixed clusters might leave only some hardware traces, and a Hopper result does not rule out subsequent Blackwell formation. Nor can the weights establish the ownership, location, or acquisition of the chips. DePue’s report notes that Blackwell systems can be rented outside of China and says that this evidence alone proves neither smuggling nor an export control violation.
AMD’s MI300X is the identified hardware alternative. It normally uses 304 processing units but can be split into two groups of 152 or configured to use 148, reproducing the layouts in physical tests. For DeepSeek-V4-Flash, 363 out of 377 retained values that differ between vendors matched NVIDIA and none matched AMD. That numerical test did not solve the problem of the other five models, although the report considers a specially configured AMD cluster to be very unlikely.
The report states that exports of B200, B300, GB200 and GB300 to China require a US license and that such licenses have not been reported; it also says that the MI300X is controlled. The method itself requires public weights and a recognizable hardware-dependent initialization model. CPU initialization leaves no GPU layout, and Baidu’s PaddlePaddle generator does not support the chip layout examined.
The analysis provides policymakers with technical evidence of access to the hardware without providing a conclusion about enforcement: public weights can expose an initialization pattern, but determining whether export controls were violated would still require evidence about where the hardware was used, who owned it, and how access was gained.
Post Comment