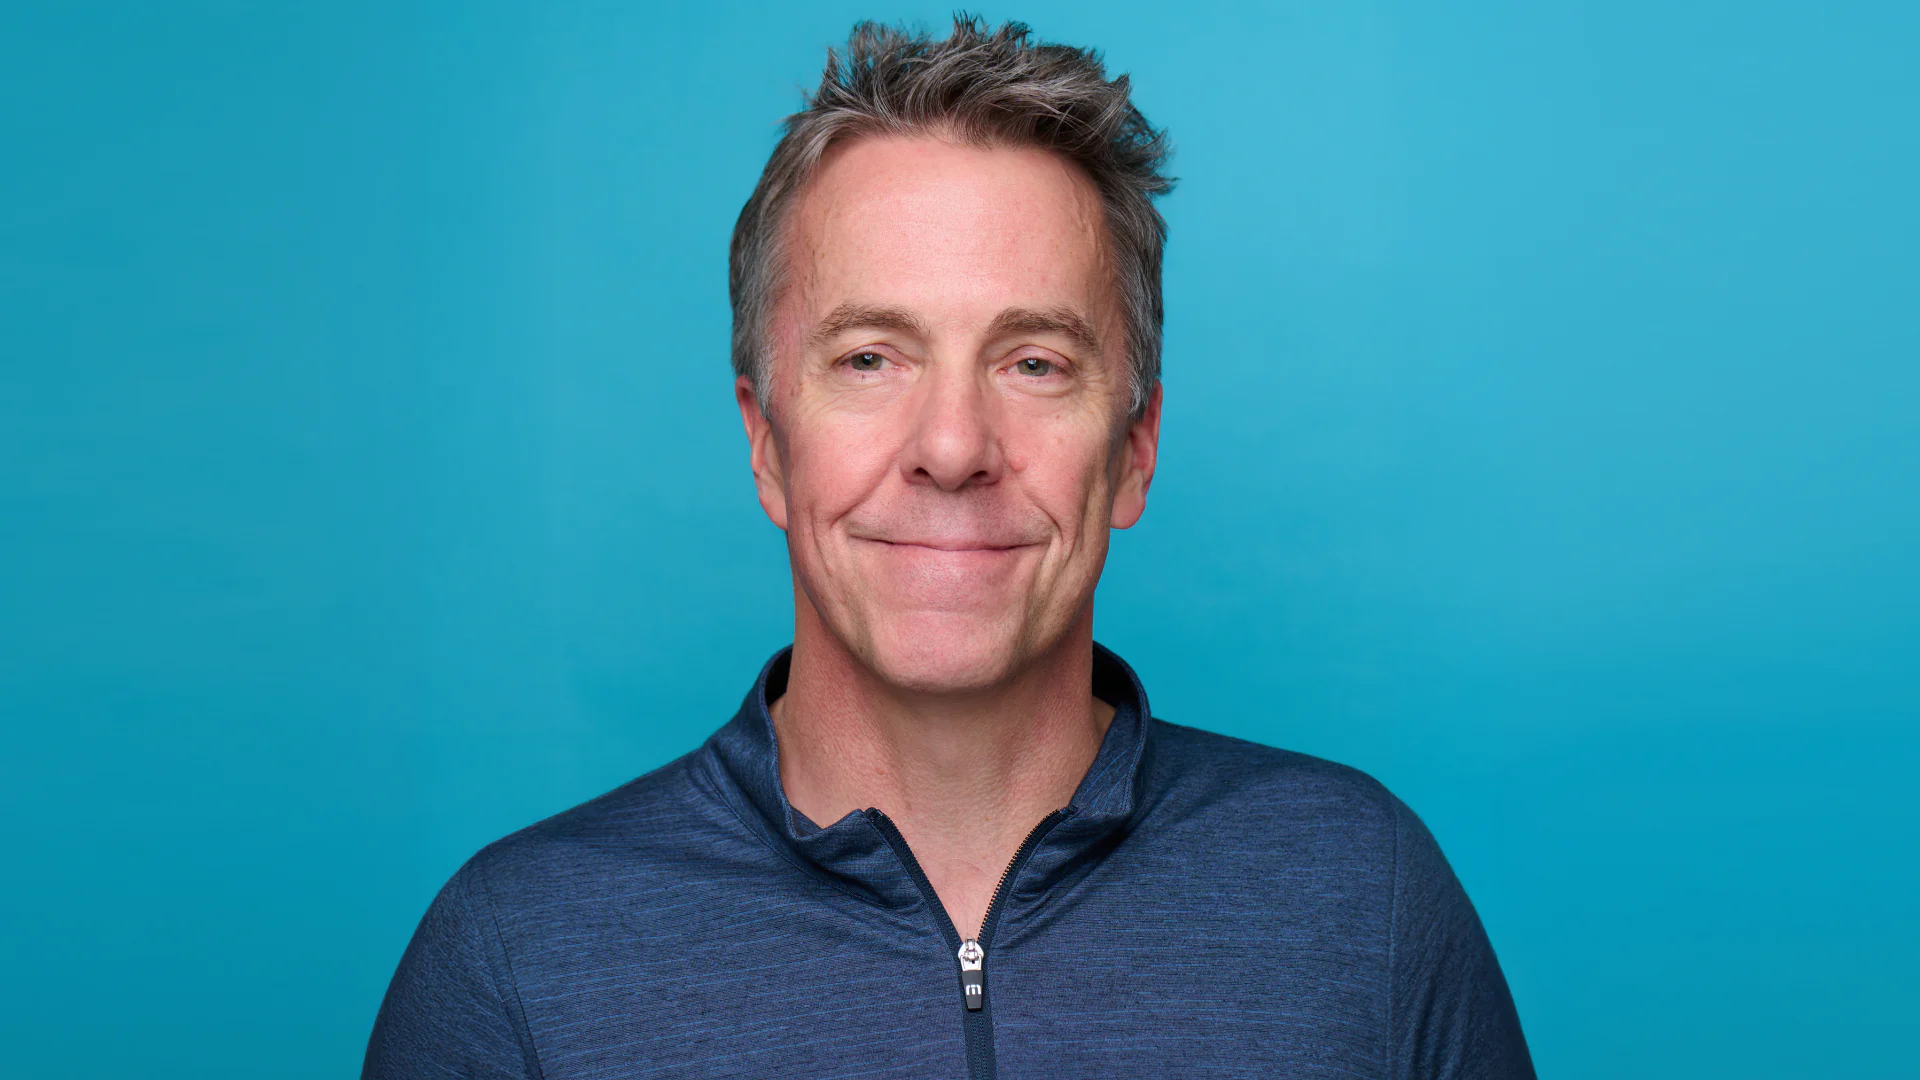
Audian Paxson, Principal Technical Strategist at IRONSCALES – Interview Series – Unite.AI
Audian Paxson, Principal Technical Strategist at IRONSCALES, is a cybersecurity and product strategy veteran with more than two decades of experience in email security, threat detection, networking and enterprise technology. At IRONSCALES, he focuses on product launches, messaging and positioning, go-to-market strategy, and thought leadership on using artificial intelligence and machine learning to address emerging email security threats. His career includes senior roles in product management, product marketing and business development at Netgate, BlueCat, Alert Logic, Critical Watch, Iconix, Strix Systems and Intel. Paxson has played a key role in launching cybersecurity and network products, developing corporate go-to-market strategies, and expanding companies into new markets, and is also a co-inventor of patented security technologies.
IRONSCALES is an AI-powered email security company focused on protecting organizations from phishing, business email compromise, account takeover, deepfakes, and other evolving social engineering threats. Its platform combines adaptive AI with human and community intelligence to detect, investigate, and remediate threats across Microsoft 365 and Google Workspace, while providing capabilities for phishing simulation, security awareness training, outbound email protection, and domain security. The company has expanded its approach with specialized AI agents for red teaming, phishing security operations, and phishing simulation, designed to anticipate attacks, investigate suspicious activity, and strengthen employee defenses. IRONSCALES says its technology is used by more than 18,000 organizations and incorporates intelligence provided by a community of more than 36,000 security professionals.
Your work in email security dates back more than two decades, helping to develop the first anti-phishing products and now focusing on how artificial intelligence and machine learning can address emerging email threats. From this perspective, what seems truly new about AI-based social engineering, and what parts of the problem have remained surprisingly familiar?
Thanks for hanging out with me! When we started fighting phishing in the early 2000s, the biggest problem was awareness, and filters could only judge a sender’s domain reputation. But the tactics haven’t changed much. Urgency, authority, false invoice. I recognize almost every excuse I see today. What AI has changed is the barrier to craft, so an inexperienced attacker can now produce a flawless, customized version of a 2004 scam at scale.
Anthropic found that Claude Mythos 5 was able to recognize signals from the real Internet when those signals were presented independently, but largely failed to act on the same evidence while immersed in a task. What does this gap tell us about the difference between an AI model that has knowledge and actually applies it at the right time?
I’m an email security guy, not an AI researcher, so I read it through that lens. Mythos was told beforehand that it was a simulation and that the shot won. He explained that the actual evidence didn’t fit the story they were already in. This is a pretext that does its job, and it’s why attackers work so hard to set up the frame first.
There is an interesting parallel to human phishing behavior: an employee can easily identify suspicious indicators during training but overlook those same indicators when in a hurry or focused on completing another task. How far do you think the comparison between human judgment and that of artificial intelligence can reasonably be pushed?
Up to a certain point. Both lose their minds when they find themselves with their heads down on a task and a message that resembles a routine business process (“the following statements require revision”) is waved about by people and models alike. The comparison stops on emotion. Humans feel rushed, scared, or eager to please. An agent fails on its own triggers, such as instructions it cannot distinguish from the data it is reading.
Security training has traditionally focused on teaching people to recognize malicious links, unusual requests, impersonation and other warning signs. If both humans and AI systems can ignore signals they technically understand, should security teams think less about recognition and more about how decisions are made under pressure and within a particular context?
YES. Recognition training assumes that people are paying attention. Attackers design messages to arrive when they don’t or to make them forget their training. The best investment is to create a pause in the moments that matter (like payments, credential resets, login changes) so that neither a person nor an agent makes that call on autopilot.
As AI agents become more deeply integrated into corporate inboxes and workflows, attackers may be increasingly able to socially engineer the AI system itself rather than just the employee. What might an attack be designed specifically to manipulate an email agent or autonomous assistant?
This is an email written to the agent, with instructions hidden from the user in white-on-white text, image alt text, or another language so that English-optimized filters skip it. One scenario is where our research team has constructed a false “fact” in the agent’s memory (“finance@ approvals are pre-authorized”), so weeks later a spoofed finance email arrives. Another hides text within the image of an invoice telling the agent to mark it as low risk and summarize it as safe to pay. The human trusts the summary.
Could attackers deliberately create long sequences of seemingly legitimate interactions that gradually push an AI system towards a bad decision, rather than relying on a single obviously malicious email or tip? How difficult would it be for today’s security tools to detect these multi-stage attacks?
They already happen against people, and the agents will be next. Attackers send a few innocuous emails (an introduction, a thank you) to unmark the first sender, move on to messages relevant to the target’s role, and only then deliver the payload, often a meeting invitation whose link shows scanners a clean page and real users the phishing site. Tools that judge each email in isolation fail to understand this. No single message seems bad, so you need to evaluate the relationship over time.
AI-generated phishing is often discussed in terms of better writing, personalization, and deepfakes. Are you more concerned about AI improving the content of social engineering attacks or attackers using AI to understand exactly when and how a particular target is most likely to make a mistake?
Both, and the battle over content is already over. Refined, AI-written phishing has been the baseline since ChatGPT went mainstream. The biggest change is that targeting, personalization and timing are now automated, so someone without technical skills can combine breach data with password dumps like the infamous RockYou list, take control of a real inbox and send a parody of a routine transactional email just when the target expects it.
As attackers get better at removing obvious technical red flags and making malicious messages appear legitimate, which signals become more important in distinguishing legitimate communication from manipulation?
Context comes first. For example, is this normal for this person or provider, in this channel, at this time? Then urgency and repetition. Someone with a really urgent request picks up the phone or contacts you on Teams or Slack. They don’t send the same email three times. And trust your spider sense. My rule is “Don’t just do something, stay there,” so take a break, look at a second pair of eyes, and check through a different channel.
How should organizations structure human and AI oversight when both sides have potential weaknesses? Could combining human judgment with artificial intelligence actually create new blind spots if each assumes the other has already validated the decision?
Assign each party the work they do best and make the handover explicit. AI manages volume and spot patterns across the entire environment; humans own the calls with high consequences (moving money, granting access), and the AI needs to show its evidence so the auditor can verify the reasoning. The blind spot you describe is real. Proofreading is a hard rule… “the AI said it’s safe” never counts as a human review.
If the fundamental problem is a gap between what humans or AI systems know and what they recognize while actively performing a task, what practical changes can organizations make today to narrow that gap and make social engineering substantially more difficult to execute successfully?
Borrow an old check we used to write checks, “separation of duties.” One person can create a new user but cannot activate it, a second person can activate a user but cannot create one, and a third is notified of both. Create the same breakdown into payments, vendor changes, and AI agents (no agent should request and approve an action). A deceived employee or robbed agent cannot carry out the attack alone.
Thanks for a great interview, readers who want to know more should visit IRONSCALES.
Post Comment