Anthropic Host’s Essay Urges AI to Return Ranges of Scientific Models – Unite.AI
Anthropic published a guest research paper on November 6, 2026, in which AI for Science grantees Jakob Macke, Daniel Gedon, and Stefan Wahl argue that LLM agents should return weighted distributions of plausible scientific models instead of a single best-fitting model. The authors are researchers from the ELLIS Institute Tübingen and the University of Tübingen.
Their central distinction is between reproducing observations and understanding a system. Many parameter settings can produce equivalent results, and different equation structures can explain the same measurements. An agent that returns an adequate response therefore hides alternatives that may support different mechanisms or predictions.
Build, constrain and interpret models
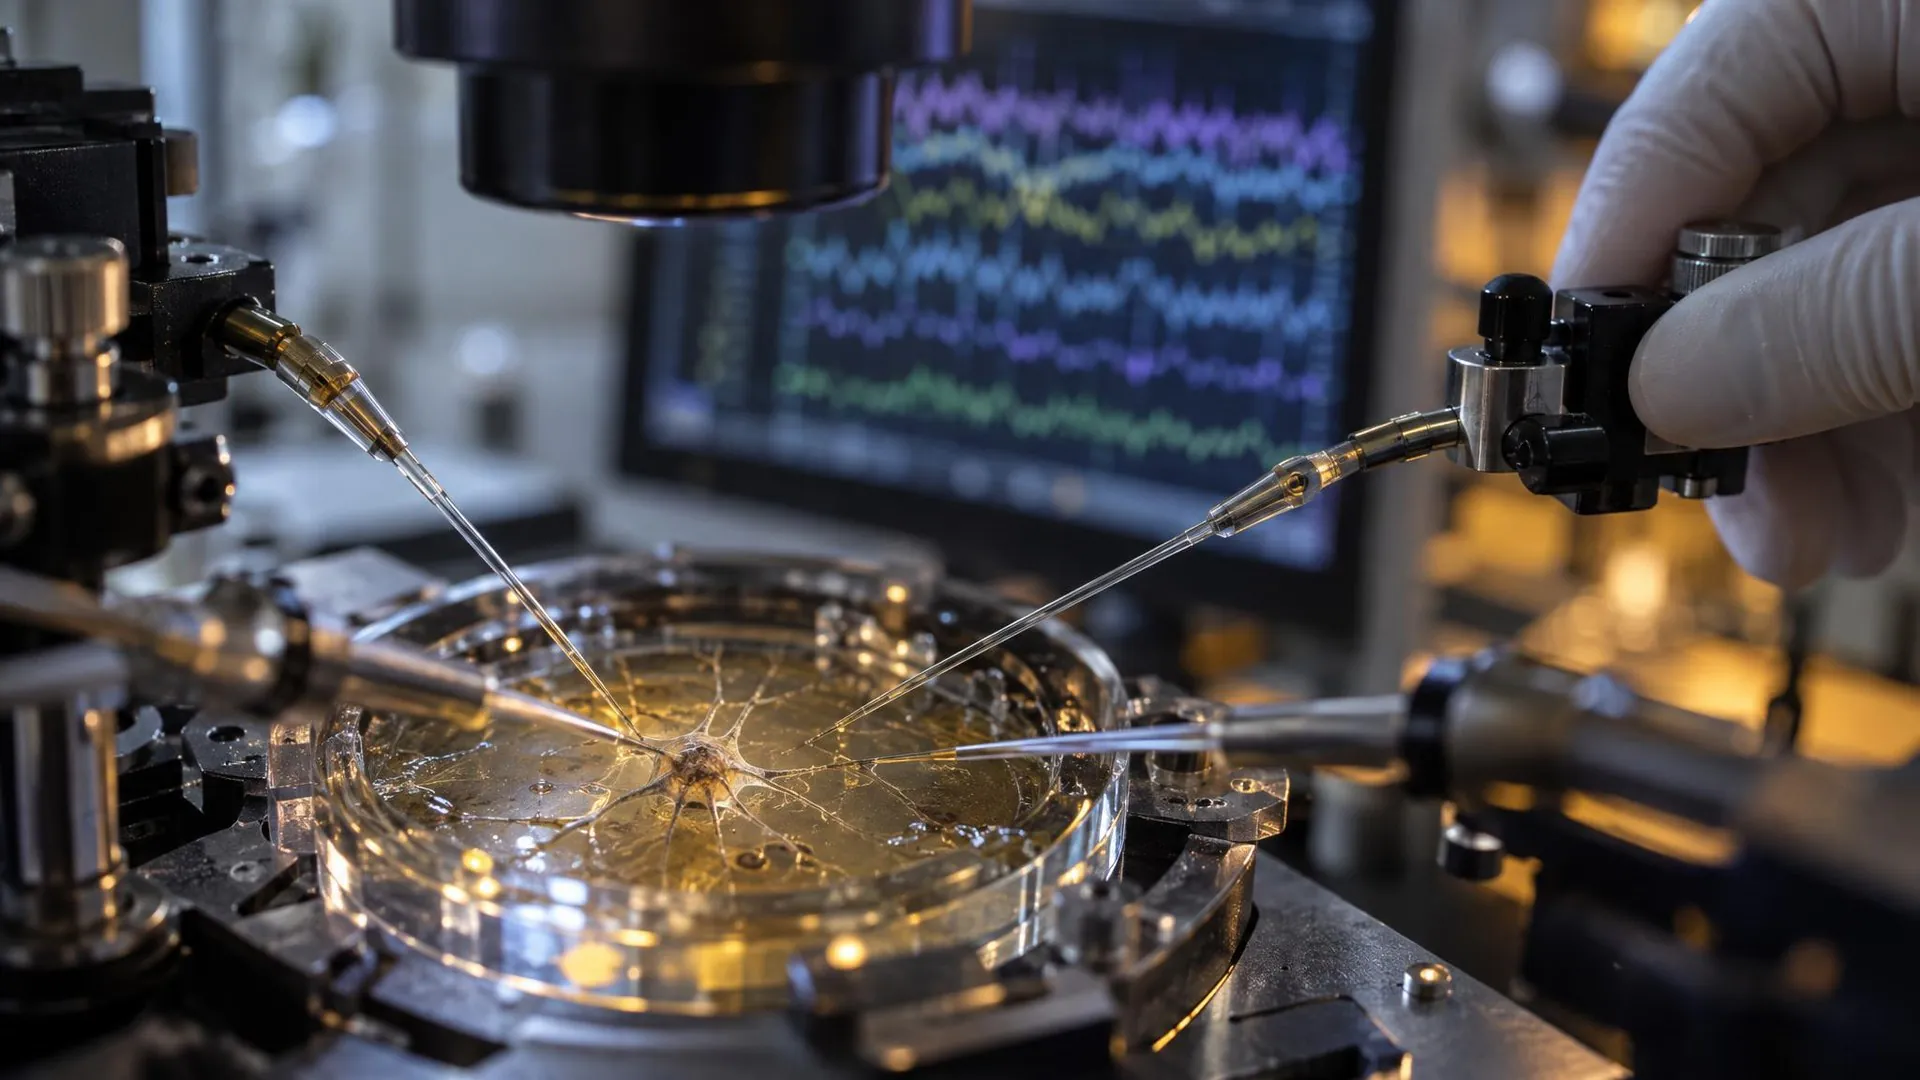
The essay divides scientific modeling into three repeated steps: building the components and equations of a model, constraining adjustable parameters with measurements, and interpreting what the result says about the real system. His historical example is Hodgkin and Huxley’s model of nerve cells. The pair chose a fourth-power term because simpler versions fit their data less well, while Huxley spent more than three weeks solving the equations with a hand-cranked calculator after the Cambridge University computer failed in 1951.
The point is that history of rejected alternatives. The fourth power supported the hypothesis of multiple moving parts in a membrane door; without knowing that the lower powers failed, numerical fit alone would not have justified the interpretation. The authors use the example to set a standard for artificial intelligence: preserving what the modeling process reveals, including failed candidates and remaining uncertainty.
From parameter distributions to model distributions
Bayesian inference addresses the parametric version of the problem by representing plausible settings as a probability distribution informed by data fitting and prior knowledge. Conventional probability calculations are often intractable for mechanistic simulators: a 2020 PNAS review explains that probability integrates implicitly over every possible execution path through a simulator.
Simulation-based inference instead samples the parameters, runs the simulator, and trains a neural estimator on the synthetic outputs. The SNPE method requires an executable model, prior parametric constraints, and observed data or summary features, without likelihood evaluations or differentiable model code. In the simulated Hodgkin-Huxley experiment, one run used 100,000 simulations to estimate eight biophysical parameters from seven voltage characteristics. Adding features narrowed the back and showed which parameters the observations constrained strongly or weakly. After the initial simulation and training phase, the learned surrogate can evaluate the new data efficiently.
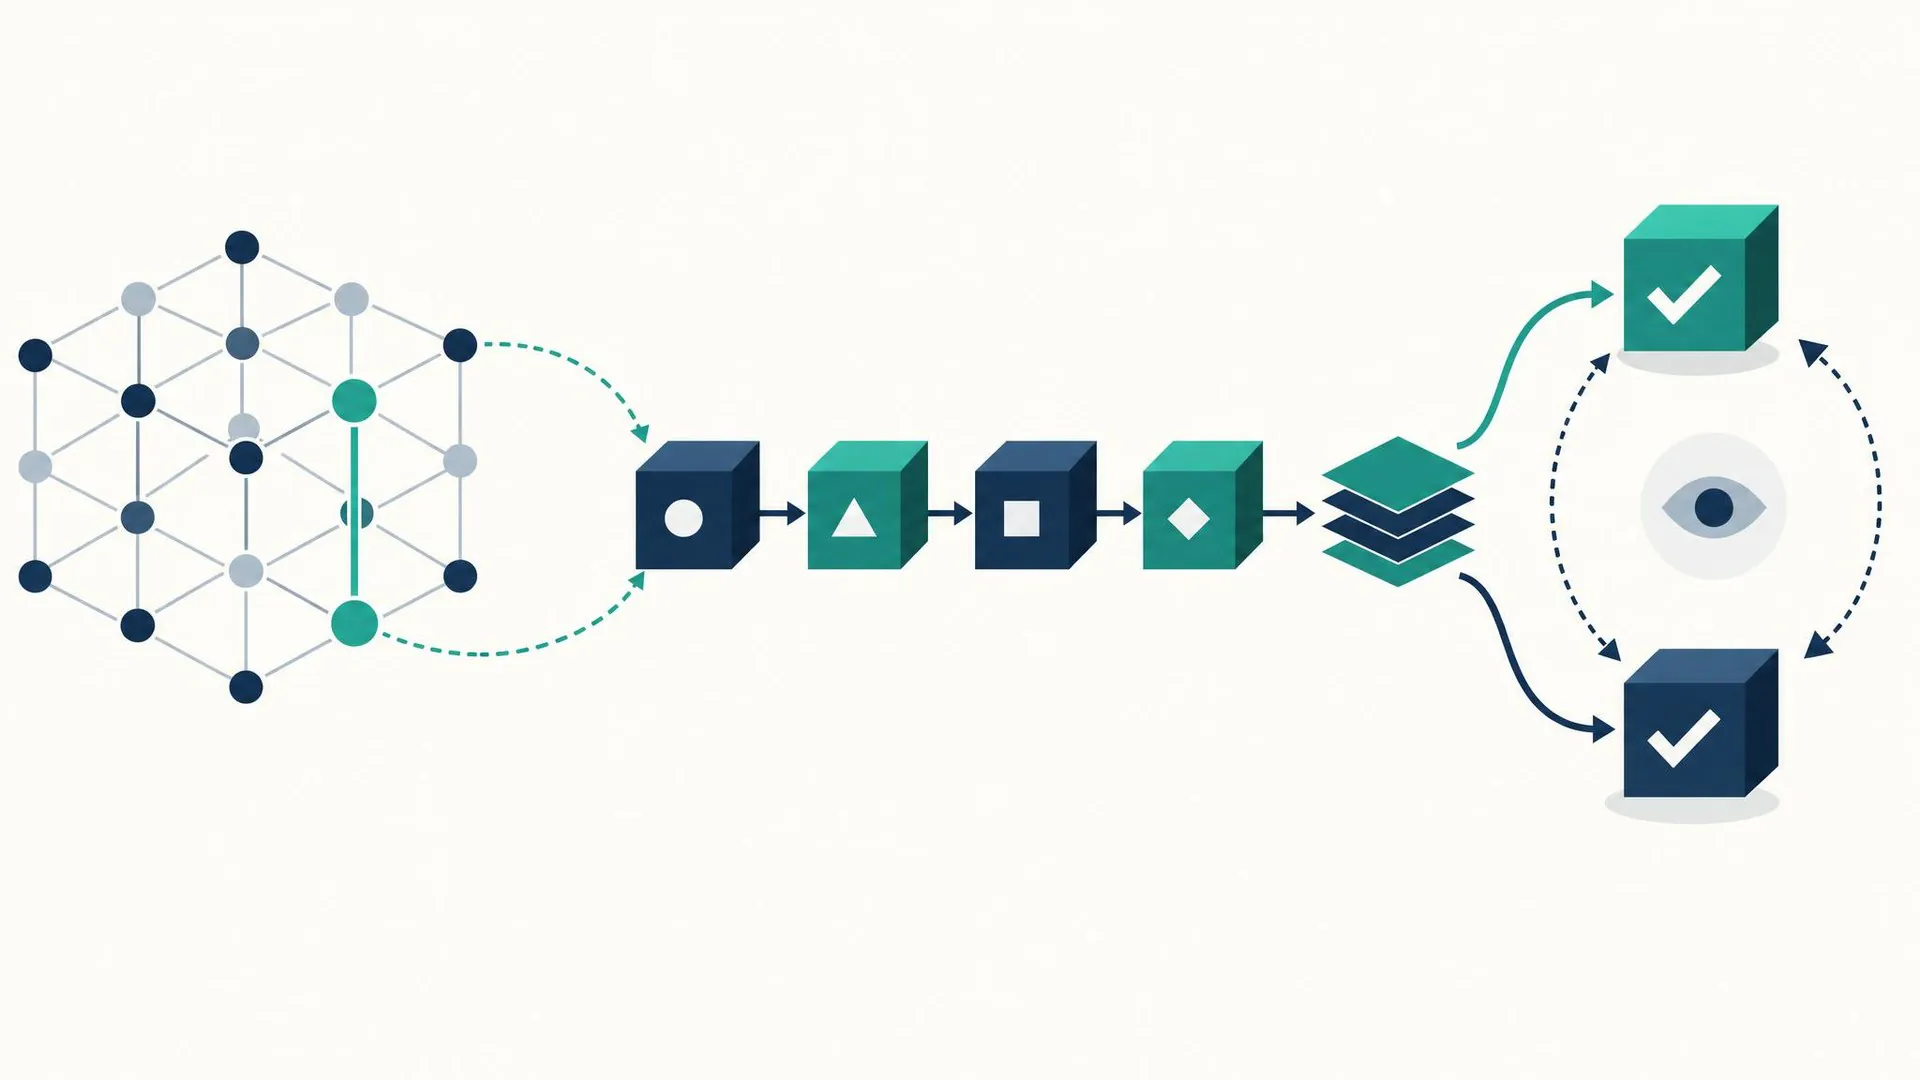
The paper extends that logic from parameters to model structures. An LLM agent can write the candidate simulator code, run it, constrain its parameters, compare the results with observations, and review the equations. Separate runs can produce different but equally suitable structures, so the proposed output is a weighted population: candidates gain weight based on data support, overly flexible fits receive less credit, and stronger candidates generate further variation. Shared characteristics among surviving models indicate what the evidence favors, while disagreement identifies poor evidence and possible next experiments.
ModelSMC searches executable models
In an earlier 2026 ModelSMC paper, Wahl and colleagues, including Macke and Gedon, formalized this approach as probabilistic inference over executable simulation programs. Each candidate is a particle proposed or refined by an LLM using ancestral implementations, evaluation feedback, and task context. Likelihood-based weights and resampling focus the population on promising structures, while parameters are marginalized during discovery instead of being reduced to a structure-optimized estimate. The work recognizes API credits through Anthropic’s AI for Science program, launched May 5, 2025, for select researchers affiliated with institutions, with a particular focus on biology and life sciences.
The experiments involved synthetic epidemiological dynamics, a simulator of aldosterone regulation in the kidneys, and a Hodgkin-Huxley structural discovery task using 10 real voltage recordings. The authors report that high-weight neuroscience models repeatedly added a slow M-type potassium current, sometimes along with another channel, and that this family ranked first in nine out of 10 analyses. Overall quantitative performance was comparable to FunSearch+ and a single-particle variant with comparable budgets; the claimed benefit is post-hoc analysis of model families rather than a uniform performance benefit.
Interpretation and validation
ModelSMC’s documented costs and dependencies matter as much as its results. Repeated simulation and likelihood estimation are computationally expensive, surrogate likelihoods can introduce bias in case of misspecification, and discovery depends on the LLM proposing useful structures. The guest essay adds a broader qualification: These systems have mostly been tested on the rediscovery of known patterns, and the evidence that they work on scientific problems with no known answer is sparse.
The authors call interpretation the most difficult step to delegate because data fit is measurable, while better understanding does not have as clear a goal. Agreement between models fitted after a system is disturbed strengthens a prediction, while disagreement exposes unresolved mechanisms and can guide the next experiment. This requirement becomes more important if AI increases historical pressure for compact, human-readable models, because larger models increase the need for explicit uncertainty and short mechanistic summaries.
The standard set by the authors therefore goes beyond a suitable model: an AI system should document the evidence behind its answer, including measurements that identify each component, candidates that failed, uncertainty left unresolved, and questions created during the search. Against this basis of limited validation, the decisive question is whether the preservation of model distributions, together with the history of rejected alternatives, produces understanding about genuinely open scientific problems.
Post Comment