MIT details CheMeleon model for low-data molecular prediction – Unite.AI
MIT News detailed CheMeleon on November 6, 2026, presenting an open-source molecular foundation model designed to predict chemical properties when task-specific experimental data is scarce. Developed by researchers at MIT and BASF, it is intended to prioritize molecules for drug and materials discovery.
The peer-reviewed paper behind the model predates the announcement. It was published online on August 7, 2026 and appeared in Journal of Chemical Information and Modelingit is the number of September 14, 2026; an earlier version was online as of 2025.
One goal is the estimation of ligand affinity for a newly discovered target cellular drug, where researchers have few measurements for the property of interest and must decide which compounds merit synthesis and testing. CheMeleon’s role is to narrow the field of candidates, not to make molecular behavior perfectly predictable.
Preformation on the calculated descriptors
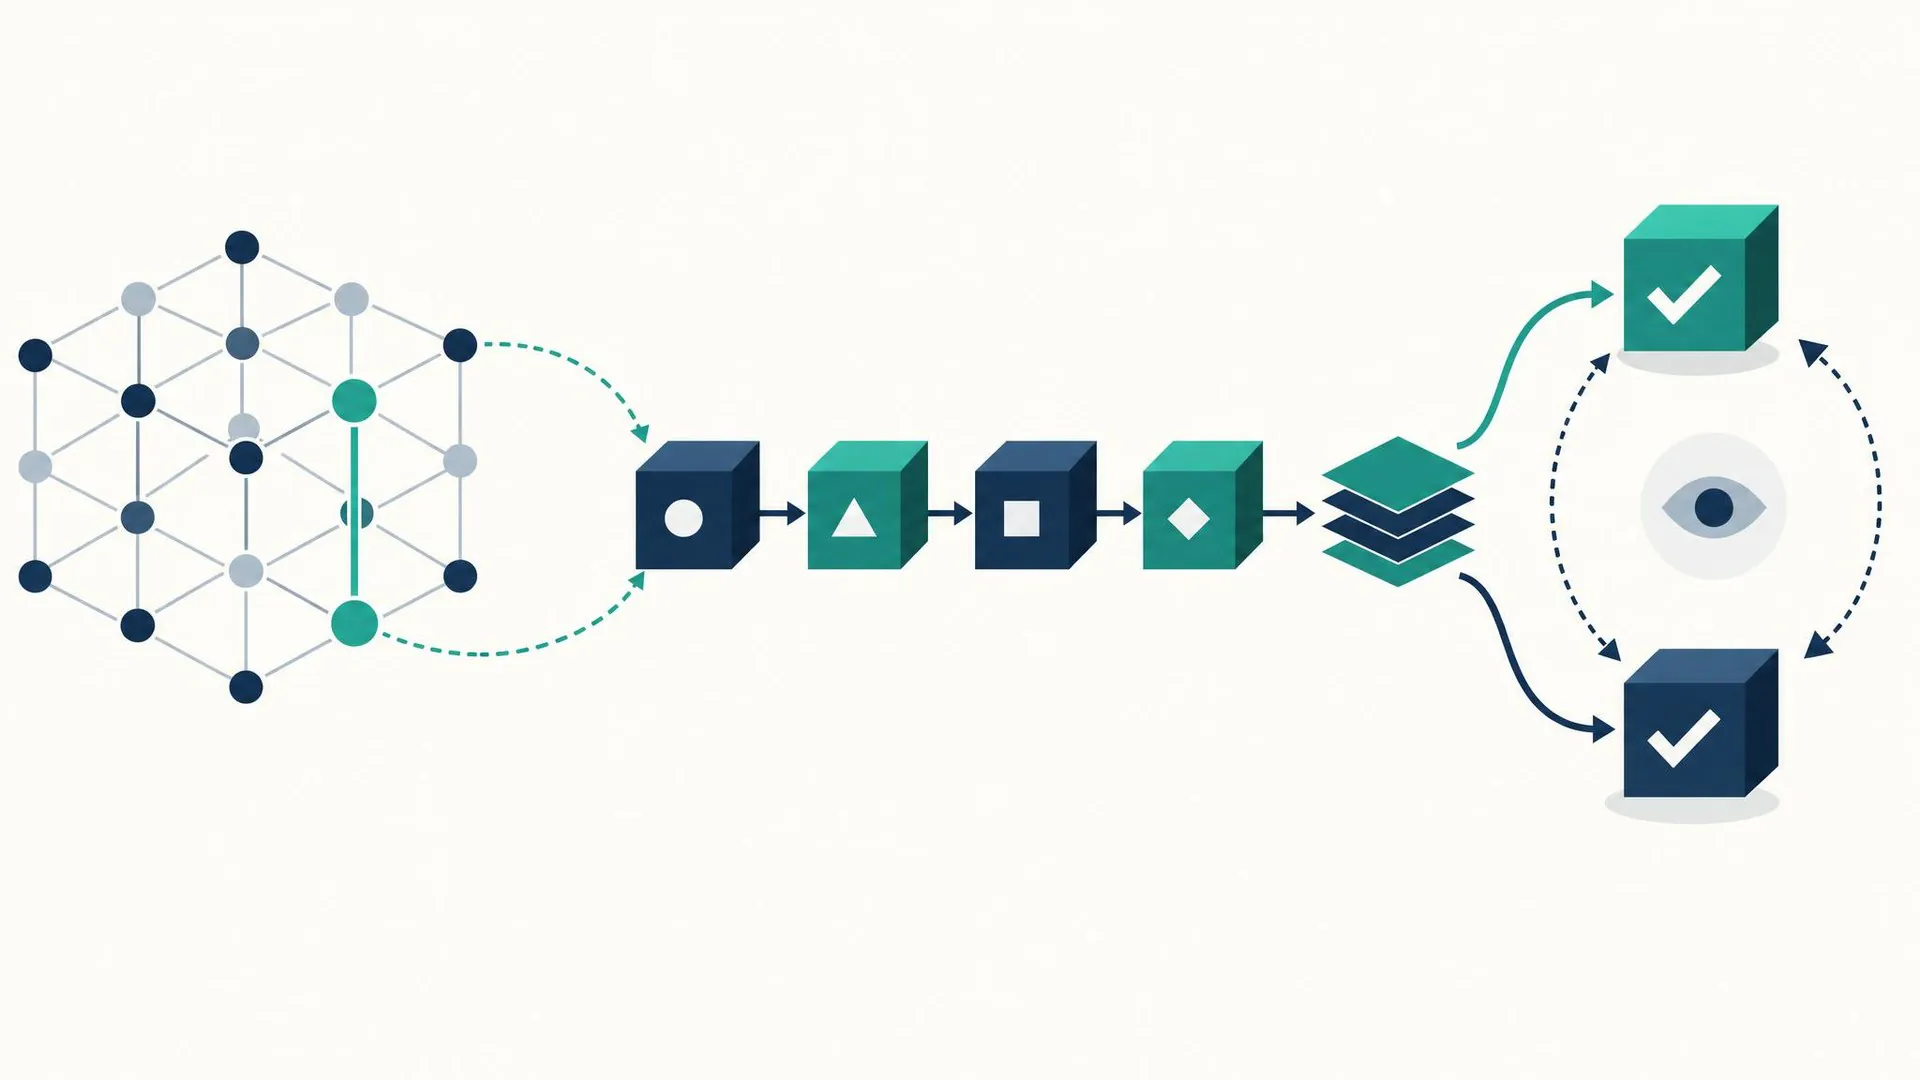
CheMeleon was pre-trained on about a million molecules by PubChem and about 1,600 molecular descriptors developed by chemists over decades. The training objectives were calculated rather than collected from published experimental literature, with examples including molecular weight and number of oxygen atoms. This supervised pre-training uses computable, low-noise descriptors to build molecular representations that can be transferred to other tasks.
The same pre-trained model can then be fine-tuned with a small amount of activity-specific data for properties such as solubility, viscosity, bioactivity, or reactivity with a particular protein or enzyme. CheMeleon is a basic model with approximately 10 million parameters, developed for direct message passing neural networks.
MIT graduate student Akshat Shirish Zalte contrasted the approach with classic expert-driven models, in which specialists manually code how descriptors such as molecular size, branching, or mass can relate to a property such as solubility. CheMeleon instead learns general chemical relationships during pre-training, so each new task doesn’t require the network to learn everything from scratch.
Benchmark results and reported adoption
The researchers evaluated CheMeleon on 58 benchmark datasets covering properties relevant to small molecule drug discovery, sourced from the industry-led Polaris benchmarking initiative. In statistical comparisons reported by the authors, CheMeleon outperformed classical baselines, including Random Forest applied to molecular fingerprints and descriptors, as well as existing baseline models.
William Green, the Hoyt Hottel Professor of Chemical Engineering at MIT, said the model dramatically reduces the number of molecules that must be tested experimentally to accurately predict the properties of new compounds, tying that advantage to the time and cost of synthesis and testing.
Green said nine of the top 20 participants in an OpenADMET competition held in early 2026 used CheMeleon in workflows to predict the properties of molecules that had not previously been synthesized.
MIT has reported its regular use by several pharmaceutical companies. Green said at least one unnamed company instructed staff to start with CheMeleon every time it modeled a property.
Open availability and practical limitations
CheMeleon and its pre-training framework are open source, and users can download and tune the model via ChemProp, a software developed and maintained by Green’s group. The project also brings together chemical engineering researchers at MIT with BASF SE scientists Jochen Sieg, Christian Feldmann and Miriam Mathea in Germany.
For discovery teams, the practical meaning is a reusable starting point when a new property has little directly relevant training data. Reported benchmarks and early adoption show that CheMeleon has moved beyond a single laboratory demonstration, but its role remains priority: the compounds it favors still require experimental work to establish their actual behavior.
Post Comment